Live · Tools · Agentic
Crawller
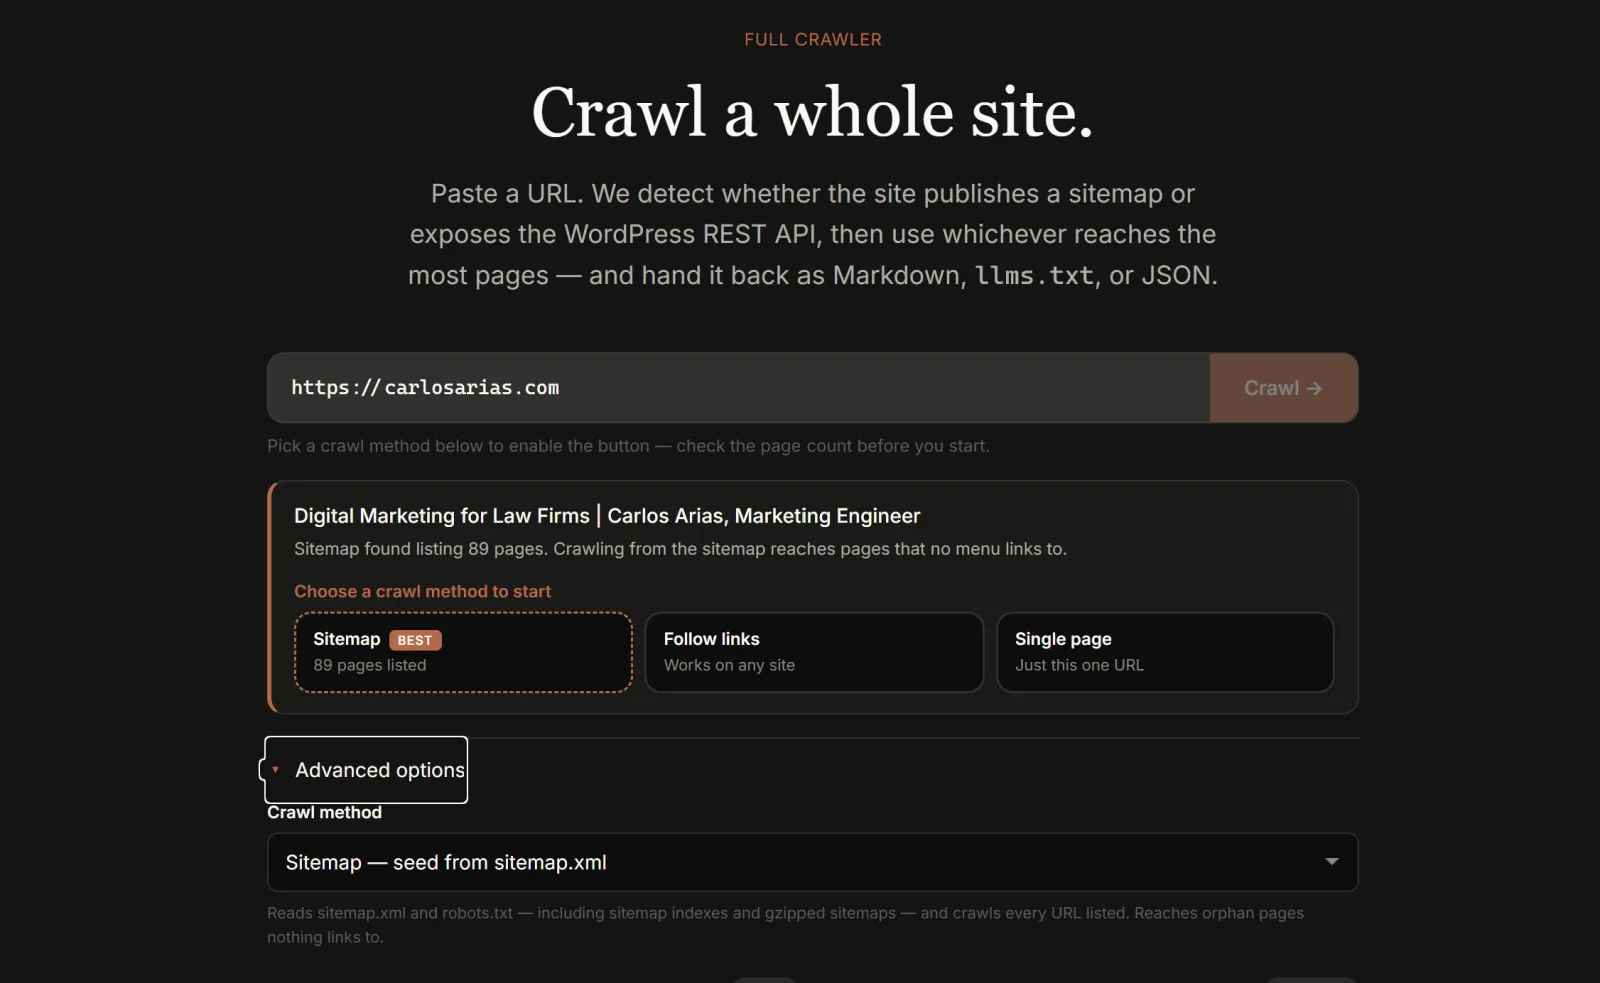
I need a crawler that could extract a text from a website for LLM learning, SEO Analysis and Brand Identity analysis. Other Crawlers couldn't do what I needed. So I built my own.
Solo, architecture and build
- Category: Tooling
- Released: 2026
The problem
Fetching pages is trivial. Turning a site into something a language model can reason over is not. Boilerplate has to go, structure has to survive, and the result has to be chunked in a way that keeps meaning intact across boundaries.
Most crawlers optimise for coverage. This one optimises for what comes after.
What it does
Large-scale collection with knowledge extraction built into the pipeline rather than bolted on afterwards. Output is indexed for retrieval, not just archived.
It is exposed to agents over MCP, so an agent can crawl and reason in one loop instead of waiting on a separate ingestion step.
Where it is
Running in production, feeding the other projects on this list.
Skills applied
Engineering
- Crawl architecture
- MCP integration
- Vector storage
AI
- Knowledge extraction
- Content chunking
- Retrieval indexing
Built with
- PHP
- MCP
- LLM
- Vector storage
More work
Nova
2026 to present
The platform this site runs on. Nova is a team of AI agents that handles the repetitive work behind digital marketing, rank tracking, local SEO, citations, competitor research, content, QA, small site fixes, so that the hours I spend go to strategy instead. It runs my own projects and client websites in production.
Medellin.co
2022 to present
A city platform for travelers, expats and local businesses. It is where I learned RAG and autonomous content generation properly, at a scale where getting it wrong was visible.
Verificaa.com
2021 to present
ID verification and fraud prevention for Latin America. It exists because verifying who you are about to do business with is genuinely hard there, and that costs people real money.